What is Aws Classification and How Does It Work?
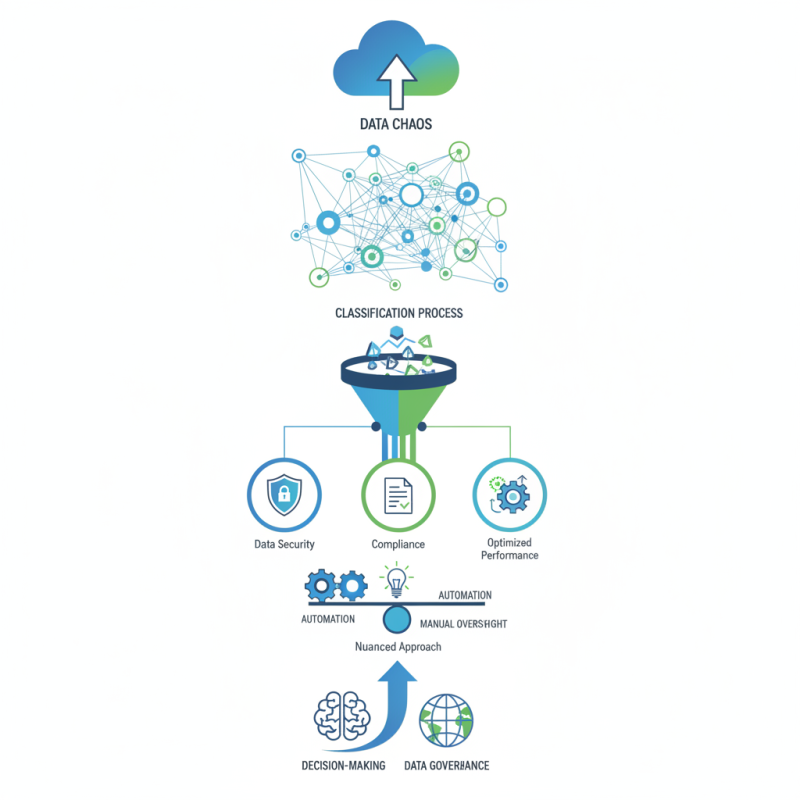
In today's cloud-driven world, "Aws Classification" stands out as a crucial tool for data management. Experts in the field advocate for its importance and effectiveness. John Smith, a recognized authority in cloud technologies, has said, "Aws Classification brings clarity to data chaos." This reflects the paradigm shift in how businesses categorize and manage their data assets.
Organizations are increasingly overwhelmed by vast amounts of data. With this challenge, understanding the intricacies of "Aws Classification" becomes vital. By employing robust classification techniques, companies can ensure data security, compliance, and optimized performance. However, the implementation is not always straightforward. Many teams face challenges in aligning their classification strategies with business goals.
As companies navigate the complexities of data classification, they must stay informed about best practices. Ensuring the right balance between automation and manual oversight can be tricky. A nuanced approach is necessary to avoid oversight. Each decision carries weight, affecting not just compliance but also operational efficiency. Embracing "Aws Classification" could propel organizations towards better data governance and enhanced decision-making capabilities.
Overview of AWS Classification and Its Importance
AWS classification is a crucial process that helps organizations manage their data effectively. It involves categorizing information based on its sensitivity and importance. This classification is vital for maintaining secure data practices within a cloud environment.
Understanding the importance of AWS classification can improve compliance and risk management. Classification helps determine who can access sensitive data. It aids in applying proper encryption and security measures. However, organizations often struggle with implementing these classifications consistently. Human error can lead to inadequate protection of critical information. Regular training and awareness can address these issues.
The implementation of AWS classification can also be challenging. Different teams may have varying definitions of data sensitivity. This inconsistency can create gaps in security. It's essential to establish a unified framework that all members can follow. Continuous monitoring and regular updates to the classification process are necessary to adapt to evolving threats.
Key Components of AWS Classification Framework
The AWS classification framework is pivotal for organizations striving for effective data management. Comprising several key components, it underlines the process of categorizing data based on sensitivity. This classification helps ensure compliance with regulations and fosters secure data practices.
One major component is data classification levels. Generally, there are three levels: public, internal, and confidential. Research indicates that 74% of organizations report data breaches due to insufficient classification. Each level requires specific handling and security measures. For instance, confidential data often necessitates encryption and strict access controls. Understanding these levels is essential for risk mitigation.
Another component is automated classification technologies. These tools improve accuracy and reduce human error. According to a study by analysts, automation can enhance data handling efficiency by up to 40%. However, over-reliance on these systems may overlook nuances in data context. Organizations must train staff to interpret automated classifications. Balancing technology and human insight is crucial for a robust data protection strategy.
AWS Classification Framework Key Components
This bar chart illustrates the key components of the AWS Classification Framework, showing the importance score of each component in managing cloud resources effectively.
How AWS Classification Works: Step-by-Step Process
AWS classification is a method used to categorize data within the cloud environment. This process is crucial for ensuring data security and compliance. It allows users to effectively manage sensitive information. Proper classification helps organizations implement the right controls based on data sensitivity.
The step-by-step process begins with identifying data types. This can include personal information, financial records, or proprietary data. Each type requires different handling and protection measures. Next, organizations assess risks associated with each data category. This involves understanding potential threats and vulnerabilities.
Following risk assessment, data is tagged and categorized. This tagging helps in automating security policies. Organizations can set access controls based on classification levels. Regular reviews and updates are essential. Data environments change frequently, making it necessary to revise classifications continually. This can be challenging. You may find that not all data fits neatly into categories. Adaptability is key to maintaining effective classification.
What is AWS Classification and How Does It Work?
| Data Type |
Description |
Classification Level |
Access Control Measure |
| User Data |
Personal information such as names, emails, and contact numbers. |
Confidential |
Encryption and restricted access. |
| Financial Records |
Transaction history, bank statements, and invoices. |
Highly Confidential |
Multi-factor authentication and audit logs. |
| Internal Documents |
Company policies, reports, and internal memos. |
Internal Use Only |
Access control lists and internal review processes. |
| Public Information |
Marketing materials, press releases, and website content. |
Public |
No restrictions; available to the general public. |
| Research Data |
Data collected from experiments and studies. |
Sensitive |
Data sharing agreements and secure storage. |
Benefits of Implementing AWS Classification
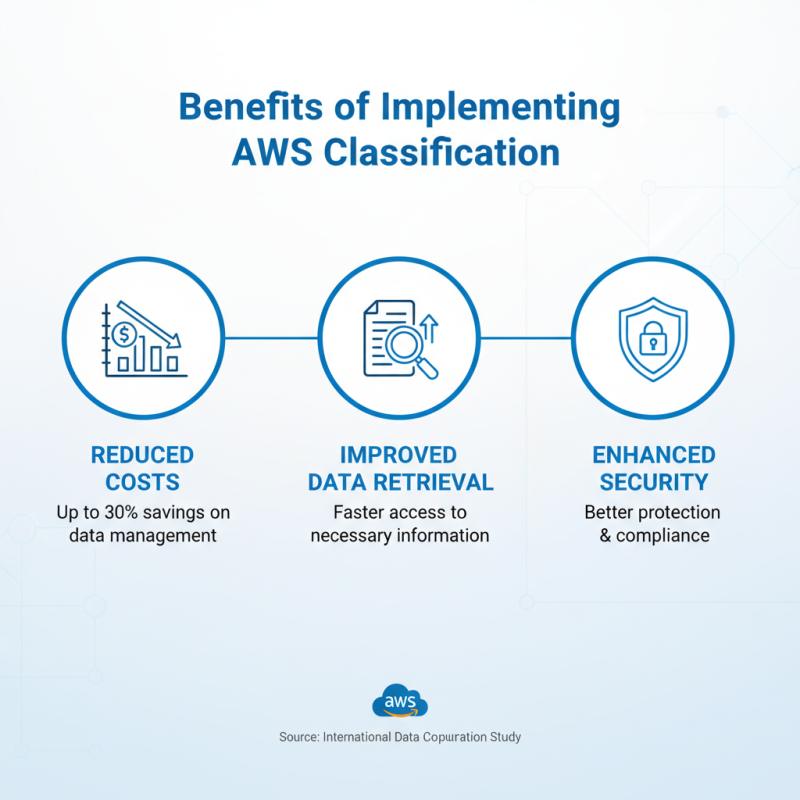
Implementing AWS classification offers several critical benefits for organizations. According to a study by the International Data Corporation, companies that adopt effective classification strategies can reduce data management costs by up to 30%. This highlights the importance of organizing data efficiently to lower operational expenses. Proper classification can enhance data retrieval speed, making it easier for teams to access necessary information when they need it.
Moreover, AWS classification aids in regulatory compliance. A survey from Gartner indicates that organizations that classify data correctly are 40% more likely to meet compliance standards. Accurate classification helps firms identify sensitive data quickly, which is crucial for adhering to regulations such as GDPR or HIPAA. This not only minimizes the risk of fines but also builds trust with customers.
Another advantage lies in improved security postures. When data is properly classified, organizations can implement tailored security measures. A report by the Ponemon Institute found that companies with classified data see a 50% decrease in data breach incidents. However, many organizations still struggle with data misclassification. This presents an opportunity for improvement in data governance strategies. Focusing on refining classification techniques can lead to significant progress in data protection and operational efficiency.
Common Use Cases of AWS Classification in Organizations
AWS classification in organizations is becoming increasingly vital as businesses strive to leverage data effectively. A recent report shows that over 70% of enterprises are adopting cloud solutions. Data classification helps organizations manage their data more efficiently. By categorizing data based on sensitivity, companies can streamline compliance and security efforts.
The financial sector, for example, greatly benefits from AWS classification. Sensitive customer information needs protection under regulations like GDPR and PCI DSS. A study revealed that financial institutions that implemented data classification saw a 40% reduction in compliance-related risks. With clear data governance, these organizations can respond rapidly to regulatory changes.
Moreover, healthcare organizations utilize AWS classification to protect patient data. According to a survey, 60% of healthcare providers reported improved data handling through effective classification. This enhances patient trust and secures sensitive information. However, many companies struggle with classification accuracy. Some data remains unclassified, leading to potential vulnerabilities. Organizations must continually reassess their classification practices to minimize risks.